Ethical, defensible hiring AI
Our promise: a highly predictive, explainable, and defensible assessment, built specifically for hiring decisions.
- Built specifically for hiring decisions
- Grounded in validated I/O psychology research
- Consistent, glass-box language analysis
Patents pending
Most AI models were not designed for hiring decisions.
Large language models (LLMs) and other black-box AI systems are rapidly being introduced into hiring workflows. But black-box models are so complex that their outputs cannot be fully explained. That's a growing concern for HR leaders and legal experts alike.
In hiring, consistency, explainability, and defensibility matter.
- Large language models were built to generate text, not to measure people
- Black-box scoring systems are difficult to explain or defend
- Inconsistent outputs undermine reliability in high-stakes hiring decisions
- Opaque methodologies increase organizational and compliance risk
Identical answers.
Wildly different results.
Generative AI models are remarkable, but their outputs are unpredictable. In our testing, even the most advanced large language models produced different ratings for the same candidate interview from one run to the next. Those aren't results you can trust or defend in a hiring decision. The TSAI Assessment always produces the same score for the same response.
Purpose-built for hiring.
The TSAI Assessment uses glass-box natural language processing (NLP). Unlike black-box AI, a glass-box approach uses transparent, documented methods, so results can be explained and reproduced, which matters when hiring decisions come under scrutiny.
No large language model or black-box AI system is used to score candidates.
The assessment combines:
- Validated I/O psychology research
- Structured interview science
- Role-specific job analysis
- Proprietary, patent-pending assessment technology
The result is a system designed for reliability, defensibility, and real-world hiring decisions.
Validated assessment science
Validated as a predictive assessment of workplace performance against tens of thousands of interviews across key industries.
Role-specific evaluation
Candidates are assessed against the competencies and traits that matter for the role, identified through job analysis, not a generic score.
Structured interview methodology
Research-backed questions aligned to the traits that matter make every response meaningful, high-quality assessment data.
Consistent, versioned logic
Stable, repeatable results, with the engine version recorded on every assessment so any result can be traced and reproduced.
More than 20 job-relevant measures from every interview.
No extra tests and no questionnaires. Every measure comes from what candidates actually say in their interview.
Competencies
The Great Eight competency framework: how candidates lead, collaborate, analyze, and get things done.
- Leading & Deciding
- Supporting & Cooperating
- Interacting & Presenting
- Analyzing & Interpreting
- Creating & Conceptualizing
- Organizing & Executing
- Adapting & Coping
- Enterprising & Performing
Personality
Big Five–based personality measures linked to workplace behavior and communication style.
- Openness
- Conscientiousness
- Extraversion
- Agreeableness
- Empathy
- Expression of emotion
Motivation & drive
What energizes candidates and how they sustain effort over time.
- Enthusiasm
- Proactiveness
- Grit
- Resilience
- Sustained dedication
- Self-determination
- Delayed gratification
- Certainty
How Fit is determined.
Identify the critical traits
Job analysis of your job description, informed by O*NET occupational data, identifies the 3–7 traits that matter most for the role.
Measure every candidate
Each candidate's interview responses are assessed across every measure, from High to Minimal. Too little evidence is reported as Inconclusive rather than guessed.
Rate Fit for the role
The critical traits combine into a single Fit result (Excellent, Strong, Average, or Low), so candidates can be compared on what matters for this job.
Built on decades of hiring science.
The TSAI Assessment is grounded in established industrial-organizational psychology research. Our validation report, including adverse-impact analysis, was authored by Dr. Michael A. Campion, one of the most cited researchers in the field, and is available to qualified organizations on request.
Research areas
- Structured interviewing
- Personality assessment
- Competency modeling
- Selection validity
- Job analysis
- Adverse impact
Validated by leading I/O psychology expertise
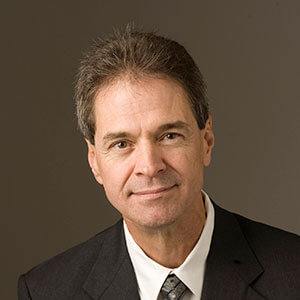
Dr. Michael A. Campion
Purdue University
One of the world's leading researchers in structured interviewing, hiring assessment, selection validity, and industrial-organizational psychology.
Designed to support people, not replace them.
People make the decisions
The TSAI Assessment informs hiring decisions. Your team makes them.
Only what candidates say
Assessment is based on the words in a candidate’s interview responses, not their face, voice, or appearance.
Clear limits
When a response doesn’t contain enough evidence for a measure, the result is Inconclusive rather than a guess.
Generative AI never scores
Where our products use generative AI for convenience features, such as drafting a job description, it never produces or changes an assessment result.
See the difference between black-box AI and scientifically grounded hiring intelligence.
Talk to our team about the validation research, the frameworks behind the assessment, and how it applies to your roles.